
Google has announced a major expansion of its linguistic technologies, now supporting everyday digital interactions in more than 300 languages spoken by over seven billion people. This milestone, which encompasses approximately 86% of the global population, marks a pivotal shift in the company’s mission to democratize information. For decades, the digital landscape has been dominated by a handful of high-resource languages, such as English, Mandarin, and Spanish, while thousands of living languages and dialects remained marginalized. By integrating advanced generative artificial intelligence, Google aims to rectify this imbalance, ensuring that technology adapts to human communication rather than forcing users to adapt to rigid technical constraints.
The initiative represents a significant evolution from the launch of Google Translate in 2006. At its inception, the service utilized statistical machine translation, which relied on large bodies of bilingual text to find patterns. Today, the platform has expanded to support more than 250 languages, fueled by breakthroughs in neural machine translation and, more recently, large language models like Gemini. The objective has shifted from mere word-for-word translation to a deeper, more nuanced "native audio intelligence" that captures the complexities of human speech, including tone, emotion, and cultural context.
The Evolution of Machine Translation: From Rigid Pipelines to Audio Intelligence
Historically, speech recognition and translation systems operated through a fragmented, multi-step pipeline. This process involved transcribing audio into text, processing that text through a translation engine, and then synthesizing the result back into audio via text-to-speech (TTS) technology. While this method allowed for basic functionality, it frequently failed to capture the essential elements of human interaction. In real-world scenarios, people rarely speak in perfectly structured, grammatical sentences. Natural speech is characterized by hesitations, overlaps, laughter, and "code-switching"—the practice of blending multiple languages within a single conversation, such as Spanglish or Hinglish.
To address these complexities, Google researchers have moved toward models that process audio directly. By training systems like Gemini on native audio data, the technology can now grasp both the sound and the intent of the speaker. This shift allows for more fluid interactions that respect the pacing and emotional resonance of the original speaker. The transition to multimodal AI means the system is no longer just "reading" a transcript; it is "listening" to the nuances that define human connection.
Bridging the Data Gap Through Grassroots Partnerships
One of the primary obstacles in expanding AI to underrepresented languages is the scarcity of digital data. Because the internet is disproportionately representative of dominant languages, traditional AI training methods often hit a "data wall" when attempting to learn languages spoken in sub-Saharan Africa, Southeast Asia, or indigenous regions of the Americas. To overcome this, Google has pivoted toward a localized, community-centric data gathering strategy.
This approach is centered on open-source innovation and grassroots partnerships. Google recently introduced "Language Explorer," an interactive tool designed to visualize LinguaMeta, currently the world’s largest open-source repository of language data. This repository maps more than 7,000 spoken, written, and signed languages, providing a foundation for researchers worldwide to build more inclusive tools.
Furthermore, Google.org has funneled resources into organizations such as the Centre for Digital Language Inclusion and AI Singapore’s Project Aquarium. These partnerships focus on gathering high-quality, localized data that reflects how languages are actually used in specific sectors, such as agriculture and healthcare. By providing farmers and medical workers with tools in their native dialects, these initiatives translate technical data into actionable community insights, fostering economic and social development.
Overcoming Infrastructure and Connectivity Constraints
While AI capabilities are advancing rapidly, the "digital divide" remains a formidable barrier. According to recent data, approximately three billion people—nearly 37% of the world’s population—still lack reliable internet access. For these individuals, cloud-based AI services are effectively non-existent. To ensure that language technology is truly universal, Google has developed TranslateGemma, a family of lightweight, open translation models derived from the Gemini architecture.
TranslateGemma is specifically designed to run efficiently on-device. This means that high-quality translation can occur without an active internet connection, making the technology accessible to those in remote areas or regions with intermittent connectivity. However, hardware remains a secondary hurdle. Hundreds of millions of people in low-resource regions continue to use "feature phones"—basic mobile devices that lack the processing power of modern smartphones.
To bridge this hardware gap, Google is supporting Viamo, a global social enterprise, to power "Ask Viamo Anything" (AVA). This voice-based AI assistant brings the capabilities of Gemini to standard feature phones through interactive voice response (IVR) technology. A pilot program in Rwanda has already demonstrated the demand for such services, with the AVA assistant answering more than two million questions from users. This allows individuals without smartphones or internet access to benefit from the same information ecosystem as those in more technologically advanced regions.
Designing for Accessibility and Non-Standard Speech
Language inclusion extends beyond regional dialects; it also encompasses the diverse ways in which people communicate physically. Conventional speech-to-text tools often fail individuals with non-standard speech patterns, requiring them to adapt their voice to the machine. Google is attempting to reverse this dynamic by building accessibility into the core of its AI development.
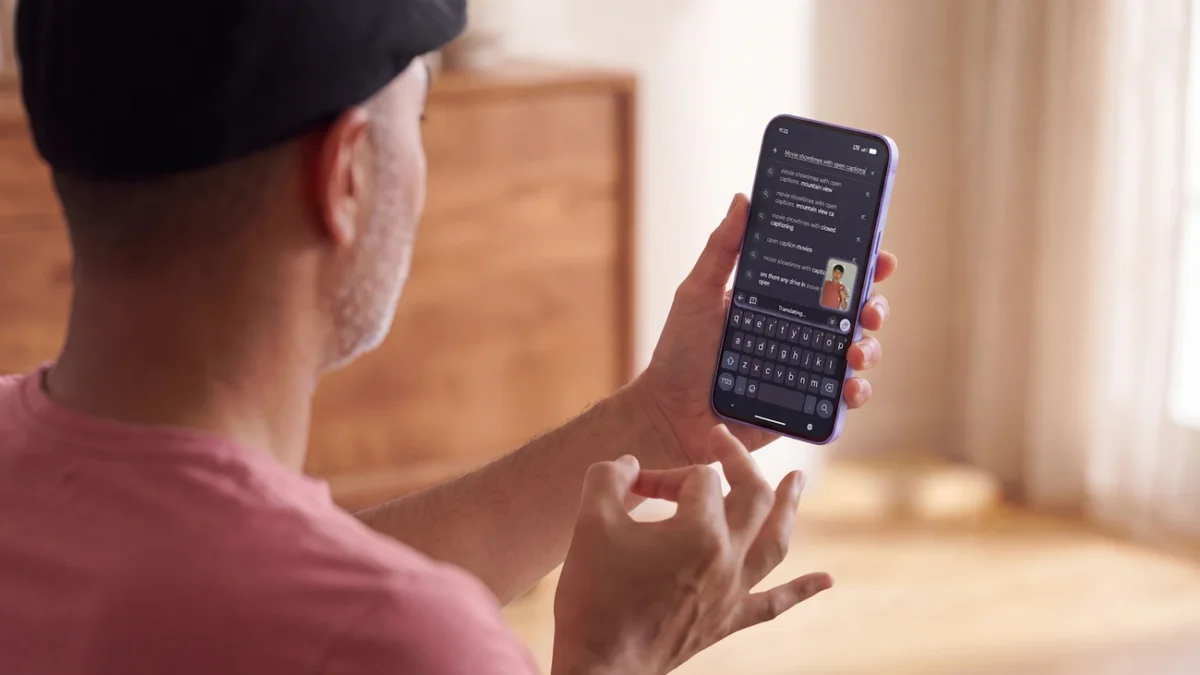
A primary example of this is the Sign Language-to-Text (SL2T) initiative. Trained on a dataset spanning over 50 different sign languages, SL2T enables sign-to-text dictation. Initially launching with American Sign Language (ASL) to English on Pixel devices, the technology allows the 70 million people worldwide who rely on sign language to communicate more seamlessly with those who do not. By integrating these capabilities into standard platforms like Gboard and Live Transcribe, Google is moving toward a future where sign language is treated as a primary medium of digital input.
Cultural Nuance and the Importance of Localized Pronunciation
A recurring criticism of global technology platforms is their tendency to "flatten" local cultures by mispronouncing names, places, and historical landmarks. In navigation tools like Google Maps, mispronunciation can be more than a minor annoyance; it can be seen as an erasure of cultural heritage.
Recognizing this, Google has begun working directly with indigenous communities to refine its text-to-speech models. In New Zealand, the company collaborated with Māori language experts to ensure that place names in Google Maps are pronounced with cultural authenticity. This collaboration ensures that the technology reflects the heritage of the communities it serves, rather than imposing a generic, Westernized phonetic structure. By incorporating these "micro-details" into its AI models, Google aims to build a sense of trust and respect with local populations.
Analysis: The Socio-Economic Implications of Linguistic Inclusion
The broader implications of Google’s language expansion are profound. In the modern global economy, digital literacy and language access are inextricably linked to economic opportunity. When a small-scale farmer in rural India or a healthcare provider in West Africa can access information in their native tongue, the barrier to entry for global knowledge is lowered.
Furthermore, the shift toward open-source data through LinguaMeta and Language Explorer suggests a move away from proprietary "data silos." By making this data available to the global research community, Google is essentially subsidizing the development of local AI ecosystems. This could lead to a surge in "hyper-local" applications—apps designed by local developers to solve specific community problems, powered by the foundational models Google has helped build.
However, the rapid deployment of these technologies also raises questions regarding data sovereignty and the preservation of linguistic purity. Critics often argue that AI models, by their nature, tend to standardize language, potentially leading to the loss of unique local slang or regional idioms. Google’s focus on "audio-native intelligence" and grassroots partnerships appears to be a direct response to these concerns, prioritizing the "richness of human expression" over standardized grammatical perfection.
Future Outlook and Global Integration
As of today, Google’s language technologies are embedded across its core ecosystem, reaching five billion people across nine major platforms, including Search, Android, Chrome, YouTube, and Google Play. The company’s strategy indicates that the next decade of AI development will be defined not just by how "smart" the models are, but by how "deep" their cultural and linguistic understanding goes.
The ongoing work with Gemini and TranslateGemma suggests that Google views language as the ultimate interface. If the company can successfully remove the friction of translation and pronunciation across all 7,000 of the world’s languages, it will have created a truly universal digital environment. For now, the focus remains on the "critical work" of reaching the final 14% of the population that remains digitally voiceless, ensuring that the next billion users can participate in the digital age on their own terms.
