
The global technological landscape reached a significant milestone this week as Google announced that its suite of language-driven products and artificial intelligence (AI) models now support more than 300 languages, effectively serving over 7 billion people. This reach encompasses approximately 86% of the global population, marking a transformative shift in the company’s long-standing mission to organize the world’s information and make it universally accessible. While dominant languages like English, Mandarin, and Spanish have historically enjoyed robust digital representation, thousands of living languages and regional dialects have remained largely marginalized. Google’s latest strategic pivot focuses on "native audio intelligence" and localized data partnerships to bridge this digital divide, ensuring that AI reflects the nuance, emotion, and cultural context of human communication.
The Evolution of Google Translate and the 1,000 Languages Initiative
The journey toward universal language accessibility began in 2006 with the launch of Google Translate. At its inception, the service supported only a handful of languages and relied on statistical machine translation, which often struggled with syntax and context. By the mid-2010s, the introduction of Neural Machine Translation (NMT) significantly improved fluency, but the gap between high-resource languages (those with vast amounts of online text data) and low-resource languages remained stark.
In 2022, Google announced the "1,000 Languages Initiative," a commitment to build an AI model that could support the world’s most spoken languages. This initiative laid the groundwork for the current expansion to over 250 languages within the Translate app alone. The transition from text-to-text translation to more sophisticated multimodal systems represents the next phase of this chronology. As AI models like Gemini have matured, the focus has shifted from merely converting words to understanding the "intent" and "sound" of human interaction.
From Rigid Pipelines to Native Audio Intelligence
Historically, speech recognition and translation followed a "cascaded" or multi-step pipeline. In this traditional model, an AI would first transcribe audio into a text format, process that text through a translation engine, and then synthesize a new audio response. While effective for simple commands, this process inherently stripped away the nuances of human speech—such as tone, pacing, hesitation, and emotional inflection.
To address these limitations, Google has moved toward native audio intelligence. By training models like Gemini to process audio directly, the system can grasp both the literal meaning of words and the speaker’s intent. This is particularly critical for "code-switching," a common linguistic phenomenon where speakers blend multiple languages in a single conversation, such as Spanglish (Spanish and English) or Hinglish (Hindi and English). Native audio intelligence allows the AI to follow these fluid shifts without the errors typically introduced during a text-transcription phase.
Industry analysts note that this shift is essential for "real-world" AI utility. Communication is rarely a sequence of perfect, grammatical sentences; it involves laughter, overlaps, and cultural idioms. By capturing these elements, Google is attempting to move AI from a robotic utility to a culturally competent interface.
Bridging the Data Gap Through Localized Grassroots Partnerships
One of the primary hurdles in expanding AI to underrepresented languages is the lack of digital data. The internet is disproportionately dominated by a few major languages, leaving AI developers with little material to train models for regional dialects. To solve this, Google has turned to a localized, community-centric approach rather than relying solely on web-scraping.
Through open-data partnerships, Google is working with local organizations to gather authentic linguistic data. A central pillar of this effort is "Language Explorer," an interactive tool that visualizes LinguaMeta, currently the world’s largest open-source language data repository. This tool maps more than 7,000 spoken, written, and signed languages, providing a resource for researchers and developers globally. The project recently received recognition from Fast Company for design innovation, highlighting its role in making linguistic diversity visible and actionable.
Furthermore, Google.org has funded initiatives such as the Centre for Digital Language Inclusion and AI Singapore’s Project Aquarium. These projects focus on bringing multilingual AI tools to essential sectors, including agriculture and healthcare. For instance, in rural regions where farmers may speak a dialect not supported by standard software, these partnerships enable the creation of tools that provide weather forecasts, crop advice, and market prices in the farmer’s native tongue.
Overcoming Connectivity and Hardware Constraints
While software advances are impressive, they are often limited by physical infrastructure. Approximately 3 billion people worldwide still lack reliable internet access, and hundreds of millions continue to use "feature phones"—basic mobile devices without the processing power of modern smartphones.
To reach these populations, Google has introduced "TranslateGemma," a family of lightweight, open-source translation models derived from the Gemini architecture. Unlike massive cloud-based models, TranslateGemma is designed to run efficiently on-device. This ensures that high-quality translation is available in remote areas with intermittent or no connectivity, a vital feature for emergency responders and healthcare workers in low-resource settings.
For those without smartphones, Google is collaborating with Viamo to power "Ask Viamo Anything" (AVA). This voice-based AI assistant brings Gemini’s capabilities to standard feature phones via interactive voice response (IVR) technology. A pilot program in Rwanda demonstrated the demand for such services, with the system answering more than 2 million questions from users. This highlights a critical implication: AI’s value is not determined by its complexity, but by its accessibility to those who need it most.
Designing for Accessibility: Sign Language and Non-Standard Speech
Language inclusion also extends to the 70 million people worldwide who communicate through sign language. Traditional speech-to-text tools are unusable for this demographic, often forcing them to adapt to technology rather than the technology adapting to them.
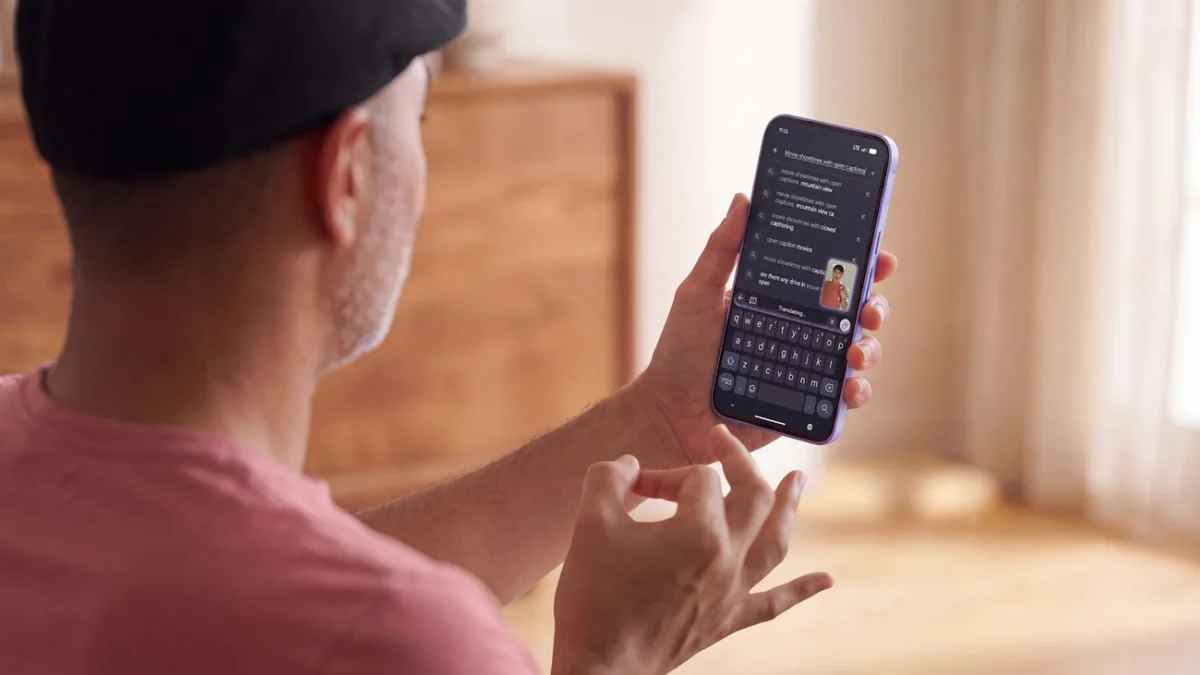
Google’s Sign Language-to-Text (SL2T) initiative aims to rectify this. Trained across more than 50 sign languages, SL2T powers sign-to-text dictation in Gboard and Live Transcribe on the Pixel 11. Initially launching with American Sign Language (ASL) to English, the technology represents a significant step toward integrating signed languages into the broader digital ecosystem.
Simultaneously, the company is refining its speech recognition to better serve individuals with non-standard speech patterns, such as those caused by ALS, Parkinson’s, or stroke. By designing for accessibility from the ground up, the goal is to ensure that AI can interpret a wide spectrum of human expression without requiring users to conform to a "standard" way of speaking.
Cultural Nuance and the Importance of Localized Pronunciation
The impact of language technology is often felt in the smallest details, such as the pronunciation of a street name in a navigation app. Mispronunciations are not merely inconvenient; they can be seen as an erasure of local heritage.
In New Zealand, Google collaborated with Māori language experts to improve the pronunciation of place names in Google Maps. By incorporating culturally authentic pronunciations directly into text-to-speech models, the technology respects the heritage of the community. This move has been praised by linguistic preservationists as a model for how global tech giants should approach local cultures—by acting as a partner rather than a top-down provider.
Broader Impact and Industry Implications
The expansion of AI language tools has profound implications for global trade, education, and social equity. As these tools become embedded across platforms like Search, YouTube, and Android—currently reaching over 5 billion users—the "language barrier" that once hindered international cooperation is beginning to dissolve.
From a business perspective, Google’s commitment to open-source tools like TranslateGemma and Language Explorer positions the company as a foundational layer for the next generation of global AI development. By providing the data and the lightweight models, they are enabling local developers in Africa, Southeast Asia, and Latin America to build their own bespoke solutions.
However, the rapid deployment of these technologies also raises questions about data sovereignty and the potential for "digital colonialism." Critics and ethical researchers emphasize that as Google gathers data on underrepresented languages, it must ensure that the benefits of that data return to the communities that provided it. The company’s focus on open-source repositories and grassroots partnerships appears to be a direct response to these concerns.
As AI continues to address society’s largest opportunities, the focus on "depth and richness" over mere "scale" will be the benchmark for success. The goal is no longer just to translate words, but to facilitate a world where everyone can participate and be understood on their own terms, regardless of the language they speak, the way they sign, or the device they hold. In the coming years, the success of these initiatives will be measured not just by the number of languages supported, but by the tangible improvements in communication for the final 14% of the population still waiting to be brought into the digital fold.
