
The mission to organize the world’s information and make it universally accessible and useful has reached a significant technological milestone as Google announced its language technologies now power interactions in more than 300 languages. This expansion means that approximately seven billion people—representing 86% of the global population—can now access digital tools in their native tongues. For decades, the digital landscape was dominated by a handful of high-resource languages, leaving thousands of living languages and dialects marginalized. The current shift toward massive multilingualism, driven by advancements in generative artificial intelligence and multimodal models, represents a fundamental change in how technology interfaces with human culture.
The announcement underscores a critical evolution in the company’s long-term strategy, moving away from simple text-to-text translation toward a more holistic understanding of human communication. While Google Translate launched in 2006 with a modest goal of breaking down basic language barriers, the integration of the Gemini model family has enabled the company to scale its offerings to more than 250 languages within the Translate app alone. However, the technical challenge has shifted from mere vocabulary matching to capturing the "richness of human language," which includes cultural nuance, emotional tone, and the complexities of real-world speech patterns.
The Evolution of Machine Translation and the AI Shift
The journey toward 300 languages has been defined by three distinct eras of technology. In the mid-2000s, statistical machine translation relied on vast amounts of bilingual text to find patterns, a method that worked well for common language pairs like English and Spanish but struggled with grammar and context. The second era began in 2016 with the introduction of Neural Machine Translation (NMT), which allowed for whole-sentence processing and significantly improved fluency. Today, the third era is defined by Large Language Models (LLMs) and multimodal intelligence, where AI is trained not just on text, but on audio, images, and cultural metadata.
Historically, speech recognition systems followed a rigid, multi-step pipeline. Audio was first transcribed into text, processed for meaning, and then synthesized back into audio if a response was required. This process was functional but inherently reductive, as it stripped away the elements that make human speech meaningful: pacing, hesitation, laughter, and emotional inflection. In many parts of the world, people do not speak in perfectly grammatical sentences; they frequently engage in "code-switching," such as mixing English with Hindi (Hinglish) or Spanish (Spanglish).
To address this, Google has transitioned to native audio intelligence. By training models like Gemini to process audio directly, the AI can grasp sound and intent simultaneously. This allows the system to understand the context of a conversation even when speakers are informal or using multiple languages in a single breath. This leap in "audio-to-audio" capability is central to making technology feel like a natural participant in human interaction rather than a mechanical intermediary.
Bridging the Data Gap Through Grassroots Partnerships
One of the primary obstacles to expanding AI to the remaining 14% of the population is the "data desert." The internet is disproportionately representative of dominant Western languages, meaning there is often insufficient digital text or audio to train standard AI models for underrepresented languages. To solve this, the tech industry has had to rethink data acquisition, moving away from web-scraping toward localized grassroots partnerships.
Google’s recent efforts have centered on three major open-data initiatives designed to empower local communities. Central to this is the "Language Explorer," an interactive tool that visualizes LinguaMeta, currently the world’s largest open-source language data repository. Recognized for its innovation in design, Language Explorer maps more than 7,000 spoken, written, and signed languages. By making this data open-source, the company is enabling researchers and developers worldwide to build their own tools, ensuring that language preservation is not centralized within a single corporation.
These partnerships extend to organizations like the Centre for Digital Language Inclusion and AI Singapore’s Project Aquarium. These initiatives focus on bringing multilingual tools to essential workers—farmers, healthcare professionals, and teachers—who operate in regions where digital support has historically been non-existent. By providing these communities with the data and tools to build their own AI applications, the project aims to foster a more equitable global digital economy.
Overcoming Infrastructure and Connectivity Constraints
While AI capabilities are advancing rapidly, the "digital divide" remains a physical reality for more than three billion people who lack reliable internet access. For these populations, cloud-based AI is essentially non-existent. To make technology truly accessible, it must function on-device, without the need for a constant high-speed connection.
In response to this challenge, Google developed TranslateGemma, a family of lightweight, open-source translation models derived from the Gemini architecture. Trained across 55 languages, TranslateGemma is designed to run efficiently on mobile hardware. This allows for high-quality translation in remote areas or during emergency situations where connectivity is intermittent.
However, even on-device AI requires modern smartphone hardware, which remains a luxury for hundreds of millions of people in low-resource regions who still rely on "feature phones" (basic mobile phones with limited processing power). To bridge this gap, Google has partnered with Viamo to power "Ask Viamo Anything" (AVA). AVA is a voice-based AI assistant that brings Gemini’s capabilities to standard feature phones via interactive voice response (IVR) technology. In a successful pilot program in Rwanda, the service has already answered more than two million questions, providing users with information on everything from weather forecasts to health advice, all through a simple voice call.
Accessibility and the Future of Sign Language Integration
Language inclusion also encompasses the 70 million people worldwide who communicate primarily through sign language. Conventional speech-to-text tools have historically ignored this demographic, forcing users to adapt to technology rather than the technology adapting to them.
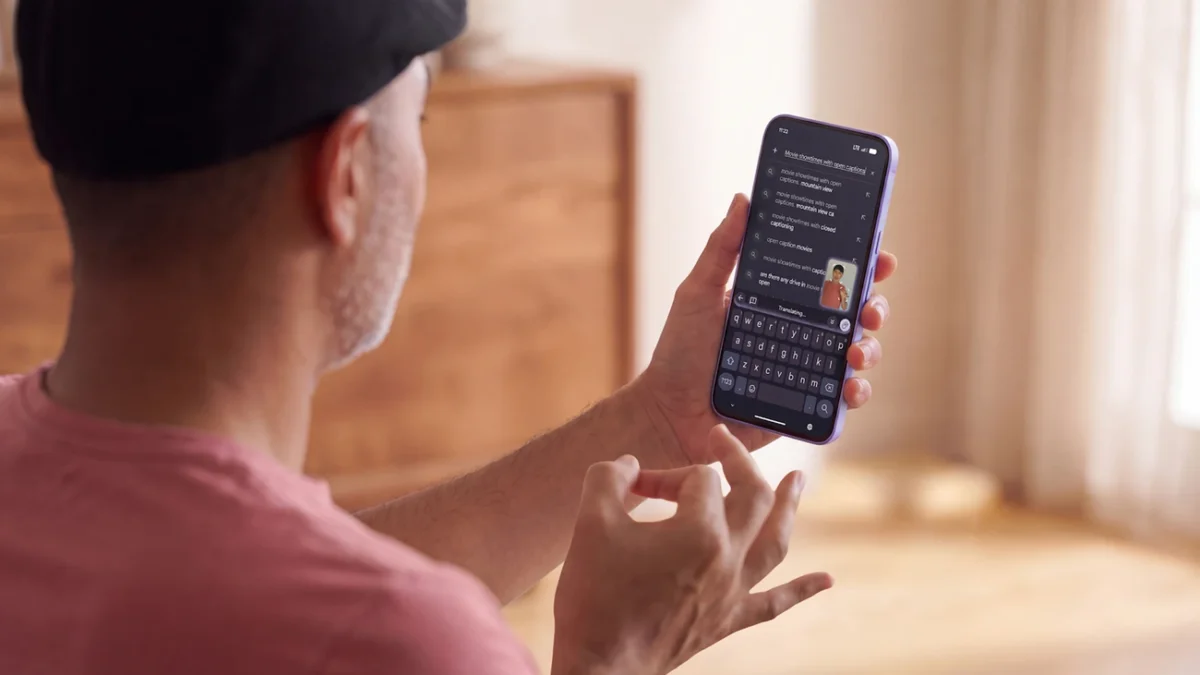
The introduction of Sign Language-to-Text (SL2T) technology represents a major milestone in accessible design. Trained on more than 50 different sign languages, SL2T enables sign-to-text dictation within apps like Gboard and Live Transcribe. Initially launching with American Sign Language (ASL) to English on the Pixel 11, the technology uses computer vision to translate hand gestures and facial expressions into written text in real-time. This innovation is viewed by disability advocates as a vital step toward full digital participation for the Deaf and hard-of-hearing communities.
Cultural Context and Localized Pronunciation
A recurring criticism of global tech platforms has been their tendency to "flatten" local cultures through standardized pronunciations and generic translations. In everyday applications like navigation, mispronouncing a town or street name is more than a minor inconvenience; it can be perceived as an erasure of cultural heritage.
To rectify this, Google has begun working directly with indigenous language experts to refine its text-to-speech models. In New Zealand, for instance, a collaboration with Māori language experts led to significant improvements in the pronunciation of Te Reo Māori place names within Google Maps. By incorporating culturally authentic phonetics into the AI, the technology reflects the heritage of the community it serves. This focus on "local intelligence" suggests that the future of AI lies not in a single, globalized standard, but in a highly fragmented, locally accurate network of models.
Broader Implications and Industry Impact
The expansion of AI into 300 languages has profound implications for global commerce, education, and diplomacy. Economists suggest that breaking the language barrier could unlock trillions of dollars in economic value by allowing small businesses in developing nations to access global markets. In education, the ability for students to learn complex subjects in their native tongue—supported by AI tutors that understand local dialects—could drastically improve literacy and graduation rates in sub-Saharan Africa and Southeast Asia.
However, the rapid scaling of multilingual AI also presents challenges. Critics point to the risks of algorithmic bias, noting that if the underlying data for a minority language is flawed, the AI may propagate stereotypes or inaccuracies. Furthermore, the reliance on "open-source" data from local communities raises questions about data sovereignty and how these communities are compensated for their linguistic contributions.
Despite these hurdles, the trajectory of the industry is clear. The goal of "AI for everyone" is shifting from a marketing slogan to a technical reality. As language technologies become embedded across core ecosystems—including Search, Android, Chrome, and YouTube—the focus is moving toward depth and richness. The objective is no longer just to translate words, but to grasp context, respect culture, and celebrate the diverse ways in which the human population communicates.
As Google and its competitors continue to push toward the "1,000 languages" mark, the ultimate success of these programs will be measured not by the number of languages supported, but by the degree to which technology allows individuals to participate in the global conversation on their own terms. The milestone of 300 languages is a significant marker in a decades-long journey, signaling a future where the digital world is as linguistically diverse as the physical one.
